Wednesday, March 9, 2016

538 Riddler: Hot New Game Show - Computing probabilities for Winning

BiggerNumberGame

ThreeFiveEight - Hot Game Show Riddler

This is an attempt at solving this ridder by the folks at 538.

This entire post is a Jupyter notebook, and it uses Python (Pandas and Numpy) to explore different aspects of the riddle.

The Problem

Two players go on a hot new game show called â€Å“Higher Number Wins.” The two go into separate booths, and each presses a button, and a random number between zero and one appears on a screen. (At this point, neither knows the other’s number, but they do know the numbers are chosen from a standard uniform distribution.) They can choose to keep that first number, or to press the button again to discard the first number and get a second random number, which they must keep. Then, they come out of their booths and see the final number for each player on the wall. The lavish grand prize — a case full of gold bullion — is awarded to the player who kept the higher number. Which number is the optimal cutoff for players to discard their first number and choose another? Put another way, within which range should they choose to keep the first number, and within which range should they reject it and try their luck with a second number?

Note: If you have attempted this problem first, then you can follow along easily and see where the approaches vary from what you attempted.

Solution Approaches

There are at least two good ways to approach this riddle. If you are a programmer and like to let the computer all the hard work, then a numerical simulation approach is the first thing that will occur to you. On the other hand, if you like to work out probabilities, then you prefer the analytical approach.

We will start with the Numerical Simulation approach, then also calculate the probabilities.

Intuition

Before we even begin calculating, our intuition strongly suggests that a player would want to use 0.5 as the cutoff. But can we prove this? This post is an attempt to see if our initial guess was correct.

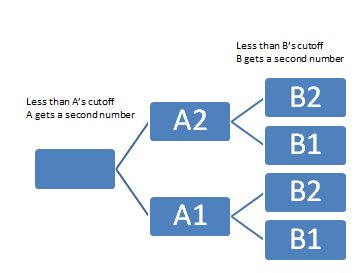
As it turns out, things are easier if we think of the events of this Game Show as a decision tree.

Decision Tree

Image of dtree

Method 1: The Numerical Simulation Approach

Let's say this game was played a million times. We can simulate that using Uniform random numbers. We can then count out the number of time each player won, under different scenarios. The scenarios in this experiment would be the different cutoffs that each player decides on.

In [154]:
%matplotlib inline
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import sys, os
In [252]:
millU = np.random.uniform(0,1,int(4e6)).reshape(1000000,4)
df = pd.DataFrame(data=millU, columns=['a1','a2','b1','b2'])
In [253]:
df.shape
Out[253]:
(1000000, 4)
In [254]:
df.head()
Out[254]:
a1 a2 b1 b2
0 0.678229 0.906019 0.140983 0.691082
1 0.242459 0.210721 0.816614 0.172865
2 0.473276 0.731607 0.710147 0.124943
3 0.289715 0.730348 0.575624 0.980886
4 0.300231 0.651216 0.122309 0.416013

Compute "Prob of Player A winning" for different CUTOFF point choices for each player

Now that we have a ready-made million row dataframe at our disposal, we can try out as many experiments as we like.

For example, we could choose a cutoff for A, and one for B, and see how often player A ends up winning.

Let's try it out. Say Player A chooses to stand at 0.2. (Meaning that if player A gets above 0.2, they won't ask for different number.) Meanwhile, Player B chooses to go for a bigger cuttoff. That player chooses 0.7 as their cutoff. In this scenario, how often will player A win?

We can do that easily by creating a couple of new columns in our dataframe, and seeing which of those two final numbers is greater. We can then convert that number to a percentage, since we know we have a million rows.

In [413]:
CUTOFF_A = 0.2 #The number above which A will not ask for another hit (second number)
CUTOFF_B = 0.7 #The number above which B will not ask for another hit (second number)

#Create two new columns
df['Final_A'] = (df['a1']<CUTOFF_A)*df['a2']+ (df['a1']>CUTOFF_A)*df['a1']
df['Final_B'] = (df['b1']>CUTOFF_B)*df['b1'] + (df['b1'] < CUTOFF_B) * df['b2']

#Finally, we create a column of True/False to denote who won
df['A_Won'] = (df['Final_A']>df['Final_B'])
prob_A_winning = (df['Final_A']>df['Final_B']).sum()/1e6
print prob_A_winning
0.460286

That seems to work. Now, we could just do this for many, many pairs of cutoffs. Which is what we are going to do next.

But before that, if makes sense to make the computation above into a Python function. Let's make it a function, so that we can call it repeatedly, giving it different A and B Cutoff values.

Writing a Function to Simulate the Win Probability

In [422]:
def prob_A_winning_simulation(CUTOFF_A, CUTOFF_B):
    df['Final_A'] = (df['a1']<CUTOFF_A)*df['a2']+ (df['a1']>CUTOFF_A)*df['a1']
    df['Final_B'] = (df['b1']>CUTOFF_B)*df['b1'] + (df['b1'] < CUTOFF_B) * df['b2']
    df['A_Won'] = (df['Final_A']>df['Final_B'])
    return (df['A_Won']).sum()/1e6

Let's test it to see if this function is working as we would expect.

In [424]:
print prob_A_winning_simulation(0.2, 0.7) #does it match what we computed before?
print prob_A_winning_simulation(0.33, 0.75)
print prob_A_winning_simulation(0.1,0.1)
0.460286
0.499826
0.499114

Running a Grid of Cutoffs

Now that we have a function ready, we can let the a and b cutoff's vary from 0 to 1, get the probability of A winning in each case, and store those. In this case, let's say that we take steps of 0.02, so there will be 50x50 = 2500 runs we make. So, the results list will have 2500 rows.

In [425]:
results = []
step = 0.02
nparray = np.arange(0,1,step)
for sta in  nparray:
    for stb in  nparray:
        results.append((sta, stb, prob_A_winning_simulation(sta, stb)))
        
        
sim_results_df = pd.DataFrame(results, columns=['A','B', 'probA']) #cast the results in a pandas df
In [565]:
#sim_results_df[sim_results_df['B']==0.5]

Logically, the next step is to examine our results data frame. We want to know the cutoffs for A which helped the most.

In [470]:
rcParams['figure.figsize'] = 3, 3 

fig = plt.figure()
data = sim_results_df[sim_results_df['B']==0.5]
data.plot(x='A', y='probA')
plt.suptitle('Win Probabilities over cutoff values, if opponent chose 0.5 as the cutoff')
plt.xlabel('cutoff for player')
plt.ylabel('probability of winning')
plt.xlim(0.48, 0.7)
Out[470]:
(0.48, 0.7)
<matplotlib.figure.Figure at 0x33ac2198>

Plotting Functions

Next, let's create a couple of plotting functions (using MatPlotLib in Python) which we can call to create surface plots. For now, you can skip over these. (Refer to them if you are interested in recreating similar plots. I have used pcolor. In the winloss plot, I use only two colors. One to show cells where the probability of winning is above 0.5, the other to denote lower than 0.5. In the other surface plot, the color indicates the probability value. 1.0 is green, and 0.0 is red.

In [661]:
def plot_winloss(rdf, step):
    from pylab import rcParams
    rcParams['figure.figsize'] = 8,8
    
    nparray = np.arange(0,1,step)
    width = len(nparray)
    fig, ax = plt.subplots()
    data = (rdf['probA']>=0.499999).values.reshape(width, width)
    heatmap = ax.pcolor(data, cmap="autumn")

    # put the major ticks at the middle of each cell
    ax.set_xticks(np.arange(data.shape[0])+0.5, minor=False)
    ax.set_yticks(np.arange(data.shape[1])+0.5, minor=False)

    # want a more natural, table-like display
    ax.invert_yaxis()
    ax.xaxis.tick_top()

    ax.set_xticklabels(nparray, minor=False)
    labels = [item.get_text() for item in ax.get_xticklabels()]
    for idx,l in enumerate(labels):
        if (idx % 5):
            labels[idx] = ""
    ax.set_xticklabels(labels, minor=False)

    ax.set_yticklabels(labels, minor=False)
    plt.show()


def plot_win_surface(rdf, step):
    from pylab import rcParams
    rcParams['figure.figsize'] = 8,8

    #step = 0.02
    nparray = np.arange(0,1,step)
    width = len(nparray)

    fig, ax = plt.subplots()
    data = rdf['probA'].values.reshape(width, width)
    heatmap = ax.pcolor(data, cmap="RdYlGn")

    # put the major ticks at the middle of each cell
    ax.set_xticks(np.arange(data.shape[0])+0.5, minor=False)
    ax.set_yticks(np.arange(data.shape[1])+0.5, minor=False)

    # want a more natural, table-like display
    ax.invert_yaxis()
    ax.xaxis.tick_top()

    ax.set_xticklabels(nparray, minor=False)
    labels = [item.get_text() for item in ax.get_xticklabels()]
    for idx,l in enumerate(labels):
        if (idx % 5):
            labels[idx] = ""
    ax.set_xticklabels(labels, minor=False)

    ax.set_yticklabels(nparray, minor=False)
    plt.suptitle('Win Probabilities Heatmap')
    plt.xlabel('cutoff chosen by opponent')
    plt.ylabel('Cutoff chosen by Player')

    plt.show()

Let's now plot our simulation results.

In [662]:
step = 0.02
plot_win_surface(sim_results_df, step)
plot_winloss(sim_results_df, step)
In [615]:
prob_A_winning(0.6,0.5)
Out[615]:
0.50490000000000002

The numerical simulation is working. Let's also try calculating the probabilities.

Method 2: Analytical Approach: Calculating the probability

Developing some Intuition

We know that the probability of a number U(0,1) beating another number in the same range: U(0,1) is half. But what is the probability if the intervals are different? We can work that out...
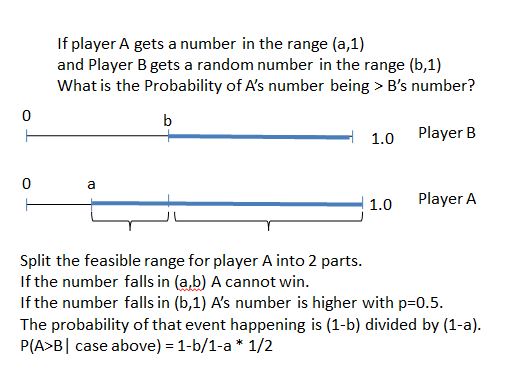
Image

If a = 0.3 and b=0.7, this works out to be (1-0.7)/(1-0.3) * 0.5 = 3/14

In [654]:
cola = np.random.uniform(0.3,1,int(1e6))
colb = np.random.uniform(0.7,1,int(1e6))
#data = pd.DataFrame({'a': cola,'b':colb})
sum(cola>colb)/1e6, 3/14.0
Out[654]:
(0.214, 0.21428571428571427)

That matches. So now, we can work out the probability for each of the 4 cases in our decision tree.
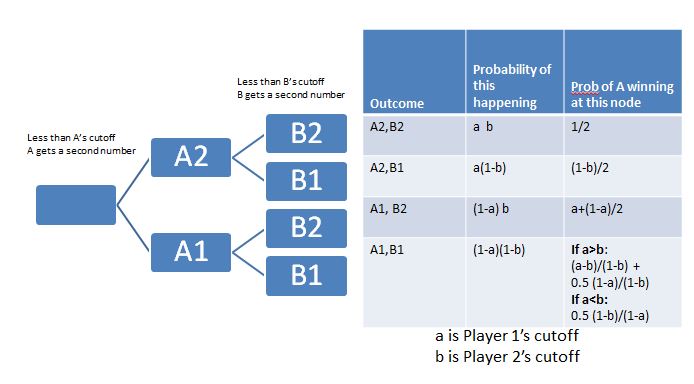
Image of dtree

In [656]:
def analytical(a,b):
    '''
    Function returns the probability of Player A winning (getting a higher number)
    if player A chose a as the cutoff, and the opponent chose b as the cutoff
    '''
    pwin = a*b *0.5
    pwin += a*(1-b)*((1-b)/2)
    pwin += (1-a)*b *(a+((1-a)/2))
    ev = (1-a)*(1-b)
    if a > b:
        p = ((a-b)/(1-b)) + (0.5 * (1-a)/(1-b))
        pwin += ev * p
    else: #a is smaller. a---1 vs b--1
        pwin += ev * ((1-b)/(1-a))*0.5
    return pwin
    

Let's see how well the analytical approach matches the numerical simulation...

In [614]:
acut = 0.6
bcut = 0.5
print analytical(acut, bcut), prob_A_winning(acut,bcut)
0.505 0.5049

That seems to match well. So looks like our analytical function is working. Now, let's just call it a bunch of times, with varying A and B cutoff values, and store the resulting probability in a results DataFrame (called 'rdf')

In [548]:
aresults = []
step = 0.01
nparray = np.arange(0,1,step)
width = len(nparray)
for sta in  nparray:
    for stb in  nparray:
        aresults.append((sta, stb, analytical(sta, stb)))
        
rdf = pd.DataFrame(aresults, columns=['A','B', 'probA'])        

Let's examine the results. We can try plotting different aspects of rdf

In [663]:
step = 0.01
print rdf.shape
plot_win_surface(rdf, step)    
plot_winloss(rdf, step)
(10000, 3)
In [608]:
meanprob = []
for a in rdf.A.unique():
    cond = rdf['A']==a
    meanprob.append((a, rdf[cond]['probA'].mean()))
    
data = pd.DataFrame(meanprob, columns=["A", 'probA'])
data.plot(x='A', y='probA')

plt.suptitle('Mean Win Probabilities over all cutoff values for opponent')
plt.xlabel('cutoff for player')
plt.ylabel('probability of winning')
Out[608]:
<matplotlib.text.Text at 0x4c834e48>
In [668]:
rcParams['figure.figsize'] = 7, 7 

fig, ax = plt.subplots()

for temp in [x * 0.1 for x in range(0, 10)]:
    data = rdf[rdf['B']==temp]
    ax.plot(data['A'], data['probA'], label = "{0}".format(temp))

plt.suptitle('Win Probabilities over cutoff values')
#plt.axhline(y=0.5)
plt.axvline(x=0.61)

plt.xlim(0.4, 0.8)
plt.xlabel("A's cutoff")
plt.ylabel("Pr(A Winning)")
ax.legend()
plt.show()

From the plot above, we can see that if a player chooses a cutoff value of slightly above 0.6, they maximize their chance of winning the game show. (I.e., no matter what strategy the opponent chooses to adopt, the first player's win probability is above 0.5.)

In [669]:
cond = rdf['A']==0.62
print rdf[cond]['probA'].min(), rdf[cond]['probA'].max()
#compared against:
cond = rdf['A']==0.50
print rdf[cond]['probA'].min(), rdf[cond]['probA'].max()
0.5 0.6178
0.4948 0.625

It looks like our intuition didn't serve us well in this case.

Tuesday, December 31, 2013

A select few posts from 2013

Rstudio's Shiny enabled me to try out ideas on the Web.


** Creating Mazes


The most visitors came from these two posts:
Happy 2014, everyone.

Ram

Monday, October 28, 2013

Anand versus Carlsen - Chennai 2013 - What can we expect in November?


This year, the world chess championship will be played between Vishwanathan Anand and 22-yo Magnus Carlsen, in Chennai, India from the 9th to the 28th of November. The passions are sure to run strong. Both GMs have ardent supporters. Carlsen is in a dreamlike form, and Anand has the experience and the home field advantage. But what do the numbers say?

Let's use R to look at some data and see what we can infer.

The data comes from chessgames.com.  I took the raw data and created two new columns to facilitate my analysis. 1. A column called Anand.White (1 or 0) and 2. a column called Anand.won (which is a factor with 3 values: 0, Draw, 1). The cleaned csv files can be found here.

1. Lifetime tally

This is always a good place to start. We have data for a total of 62 games. Anand has a slight lead on this count, with 3 more wins than Carlsen. (Not distinguishing between rapid and standard games here.)

In R, we can simply run the table() command on the Anand.won column.

 Loss  Win   Draw
  11   14     37 

2. How has each GM grown in strength

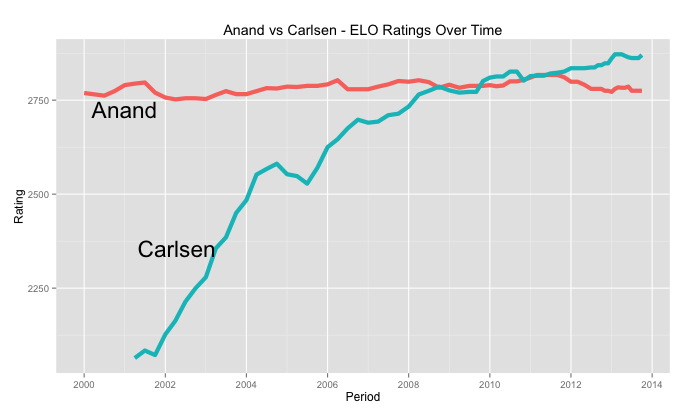
We can use ELO ratings since 2000 to see how both GMs have performed over time. Anand, of course, has been in the top 5 in the world for the past two decades, pretty much since Carlsen was born! But the visual showing Magnus' meteoric rise is quite striking. (The data comes from FIDE.com and can be found here.)

3. Win-Loss-Draw record by Year

Let's say we want to look, year by year, how the two GMs have fared against each other. R has this great package called "plyr" which is tailor made for these kinds of "Split-Apply-Combine" type analyses. We are splitting the data by year, and combining based on win-loss, and plotting the tallies. The plotting package ggplot plays well with the output of plyr.


Once we do the plotting, we get a sense of what has been happening. In the early 2000s, Anand had a much higher share of wins. Overall the number of draws has gone up over the years. But Carlsen has had the upper hand the last year or two. (Of course, the number of games is too small, and we should be careful about "inferring" when the data is this tiny.) That said, we could make a strong the case that Carlsen has the momentum going for him.

4. Choice of Openings

Finally, we know that both GMs are holed up somewhere with their team of seconds and coaches, preparing. What do these experts prepare? A good majority of the times they are preparing opening surprises to spring on their opponents. They are studying each others' games looking for weaknesses. By looking at how their choice of openings helped them in the past, we can make a broad guess about what they might go.

R allows us to slice the data by their choice of openings, and we can see how they fared.

So we can expect that Anand will favor the openings that have more "green" (wins) for him, while Carlsen will try to play the openings that have been "red" (losses) for Anand.

By this logic, we can expect Anand to opt for the Queen's Gambit Declined-semi-slav(D47), the Ruy Lopez, closed (C96)  or the Sicilian closed (B23). Magnus will be trying to steer the game towards the English (A20) or the Benko (A58) which are slightly more unorthodox, but have served him well against Anand. The expansions behind the ECO list can be found here.

Of course, there will always be surprises. (This is where it all gets game-theoretical. If only it were this easy to predict...) And that's why we should watch what unfolds this November.

The R code used can be found here.

Ram

Monday, August 26, 2013

Using R to visualize Karpov-vs-Kasparov Lifetime winner-take-all tally

The Karpov vs. Kasparov rivalry holds a special place in the chess world.

The idea behind this analysis is simple. If we take their lifetime games, plot the wins, what would it look like? We introduce one twist -- we'll be plotting the "winner-take-all" tallies, meaning that for every year, every five years, and every decade, we declare one person to be the 'winner'.

First, a note of caution: "Winner-take-all" type analyses lose a lot of information due to the roll-up. Whether a GM wins by 1 game, or a dozen games in a given year, he still gets only one "win".

At the outset, I must mention that this is NOT a chess exercise. I am ignoring the colors (whether each player had White or Black pieces) and even more egregious, I don't differentiate between standard and rapid games, or exhibition games. Time controls are ignored, as are openings.

This is a visualization exercise, and the idea is to see how it all looks when plotted.

I scraped the data from chessgames.com - where they have 201 games that the two have played. (I cleaned up the data and the csv file is available in github for anyone who wants to do their own analysis.) I use plyr to aggregate the data, and ggplot for the visualization. I wanted to try out this "pianogram" type visualization, where each plot looks like piano-keys.

Let's get the basics out of the way:

201 games - 138 draws,  37 wins for Kasparov, 26 for Karpov

Overall, Kasparov pretty much dominated Karpov. But how are these wins and losses spread across time? The two played for a little over 30 years.

The Winner-Take-All Method
In any given time period, say 1990, there can be 4 possible outcomes:
No games played, Equal number of wins, Karpov won, or Kasparov won. (If both players had the exact same number of wins in a given time period, we label that a Draw.)

Thanks to the 'plyr' package and ggplot, we can calculate the by-year, "5-year Winner" for each half-decade, and also the decade-wise winners by writing one function, and calling it with ddply.


So here's what the Yearly-Winner-Take-All looks like:

Let's plot the half-decade and decade plots. Again, note that only one GM is declared the winner for the entire decade, no matter what the difference in the scores are.


Now, we can put it all together, in one graph.


As a very quick summary, we can see that Karpov started out strong, the entire 80's was a draw, and then Kasparov took over.

The complete R code to reproduce this analysis is available in this gist, along with the data-file in CSV file.


Wednesday, August 21, 2013

What are the hottest areas for CS Research? (Based on Google Research 2013)

What are some of the hottest areas of research in Computer Science at the moment (August 2013)? And at which universities is this research being carried out?
The answers are subjective by definition, but looking at the numbers behind the Google Research awards announced yesterday can provide some quick insights. Going by the grants as a proxy for what are where are the current hottest areas of research, here's what we get:

A total of 105 grants were awarded. 81 universities in all got the awards, in 19 different research areas.

Here are the top research areas:


As far as institutions go, MIT, Georgia Tech and CMU got 5 grants each, with Cornell and Standford getting 3 each.

The R code I used to generate this can be found here. In case anyone is interested in performing their own analysis, I've also included the CSV data file.


Friday, July 19, 2013

Using R and Shiny to create “Art”

One big strength of packages like shiny is the ability to easily vary parameters and view the results, especially in plots.

So here’s a small shiny app that I created to learn about reactivity, while also having fun.


The idea is simple. Vary many aspects of geom_segments in ggplot, and see what emerges. The things that I played with are canvas size, line origin and destination, line length, the angle and the colors.

Because it is art, I made the background black.

There were many experiments that didn’t appeal to me aesthetically. Others seemed very repetitive. The ones that seemed okay, I kept.

Take a look at the shiny app ShinySketch.

here:

The code can be found on github.

Wednesday, July 3, 2013

Using R and Integer Programming to find solutions to FlowFree game boards

Using R and Integer Programming to find solutions to FlowFree game boards


What is FlowFree?
A popular game (iOS/Android) on a square board with simple rules. As the website states: Connect matching colors with pipes to create a flow. Pair all colors, and cover the entire board to solve each puzzle in Flow Free.

If you play a few games, you will be able to follow this post better. The games get progressively harder as you increase the board size.

 The solutions to the various levels are available on the web, but it is fun to use R (and the lpSolveAPI package) to come up with solutions ourselves.

So let's say that the board is made up on n "cells" (small squares) on each side. A pipe can enter a cell from the center of any side. So each cell has 4 edges.

 Figure: A cell with 4 edges meeting at the center

Terminal cells - Those cells where a colored-strand begins or ends. (Only one edge can be on in that cell.)

The 'rules' that we need to incorporate into our IP model
* The lines cannot cross.
* All the cells (squares) must be covered
* The colored lines must begin and end where they are shown

Decision variables

The problem comes down to deciding which edges to turn on, and which ones to leave off. An edge has a color and a cell. X_cke is 1 if edge e of color k in cell c is valid. 0 otherwise.

The constraints in English

  1. Cell Cover Constraints: Every cell has to have 2 edges that turned on. (One to come in, one to exit) 
    1. Special case: Terminal cells have only one edge that can be 1. All other edges are 0. 
  2. An Edge can have only one color (LimitEdge constraints) 
  3. Horizontal Connectivity - If two cells are horizontal neighbors (side by side), then the value of the east edge of the left cell must be the same as the west edge of the cell on the right. 
  4. Vertical Connectivity - If two cells are vertical neighbors (one on top of the other), then the value of the downward edge of the top cell must be the same as the upward edge of the bottom cell 
  5. Boundary Edges - Certain edges for the cells in the boundary of the board are made zero. (For example, in the 4 corner cells, at most 2 edges can be 1.) 
  6. Single color in Terminal Cells - Each terminal cell has a pre-determined color given to us as input, so we can set of the edge varibles of every other color to be zero.
  7.  Same color per cell & Pick 1 constraints. We set 0/1 variables and make sure that if a color is one inside a cell, ONLY that color edges are allowed in that cell.  (These are dense constraints and can make solution times explode for larger grids.)

Load one specific Puzzle


All of the work of  creating the matrix, the right hand side are done by 3 functions - init(), populate.Amatrix() and defineIP(). [See github for the code] Now, let's initialize an empty data frame, based on number of constraints and variables that the IP will have.


Getting the problem ready for LPSolve


After using lpSolveAPI's solve() function, we plot the solution using ggplot2 to recreate the board and show the pipes in them.

Let's try one problem:

>plotProb(terminal.cells, colorpalette)


Here are the 8 terminal cells for this problem:
> terminal.cells
  X Y color palette tcell
1 1 2     1   green     6
2 5 4     1   green    20
3 1 1     2    blue     1
4 2 4     2    blue    17
5 3 4     3  yellow    18
6 4 2     3  yellow     9
7 3 1     4     red     3
8 4 4     4     red    19

We create the linear program, and solve it using lpSolve

Let's see how many edges have non-zero values:
> lpff <- make.lp(nrow=n.row, ncol=n.col)
> defineIP()
> lpff
Model name:
  a linear program with 500 decision variables and 458 constraints
> solve(lpff)
> sol <- get.variables(lpff)
> sum(unlist(sol[1:num.edges]))
[1] 42
> plotSol(terminal.cells, colorpalette)
 
 produces the solution:


And here's the solution when I tried an 8x8 (Level 17) grid:

Note: Because of same-color and pick-1 constraints, this problem explodes in size as n (the size of the grid) increases. There are however, ways to address it, using relaxation.

Future Improvements: The addition of the pick-1 and the same-color constraints spoil the structure of the A-matrix and increase the solution time. These can be made optional, in which case the solution will require manual intervention.


You can download the full R code from github.

Useful Links:
1. Linear programming in R: an lpSolveAPI example (fishyoperations Blog)
2. Using lpSolve from R (I started with their working example)